The Kelly criterion tells you the exact fraction of capital to put behind an edge so that long-term geometric growth is maximized. Full Kelly is the math answer, not the practical one: it runs so hot with volatility that most professional users cut it to a quarter or half. The rest of this piece shows the formulas, walks through worked numbers, and gives you a workflow to size positions without blowing up your own portfolio.
TL;DR:
- Using fractional Kelly (25 to 50%) helps reduce the volatility and drawdowns associated with full Kelly while retaining most of the growth potential.
- Kelly calculations are highly sensitive to input errors, so conservative estimates, regular re-estimation, and capped position sizes are essential to practical application.
- Full Kelly often suggests leveraging above 100%, but such leverage can be dangerous if inputs are inaccurate or untested in real markets.
- Kelly-based strategies tend to outperform fixed allocations over long periods, but their real-world success depends on accurate edge estimation and disciplined sizing.
- Combining Kelly with risk-based and volatility-targeting methods creates a more robust, less risky portfolio management approach.
Table of Contents
- What Kelly Criterion Investing Actually Calculates
- How to Compute Kelly Position Sizing Step by Step
- Full Kelly vs. Fractional Kelly: What the Simulations Show
- The Estimation Error Problem and How to Guard Against It
- Extending Kelly to a Full Portfolio
- A Step-by-Step Workflow for Conservative Kelly Sizing
- Does Kelly Sizing Actually Work Historically?
- Kelly vs. Utility Optimization and Other Sizing Frameworks
- Why Fractional Kelly Beats the Textbook Version in Practice
- How Oracle Investments Speeds Up Kelly-Style Position Sizing
- Sources
What Kelly Criterion Investing Actually Calculates
Kelly criterion investing starts as a betting formula before it becomes a portfolio tool. For a simple binary wager, the fraction of your bankroll to stake is:
f = (bp − q) / b*
Here, p is your probability of winning, q is the probability of losing (1 − p), and b represents the net odds received on a win (a bet that pays 2 to 1 has b = 2). Feed in a real edge and the formula spits out a real number. Feed in a guess and you get a confident-looking number attached to nothing.
Stock and portfolio applications use a different, continuous version derived by Robert Merton for markets where returns are roughly normal:
f = μ / σ²*
μ is expected excess return over the risk-free rate, and σ² is the variance of that return. There's a clean intuition behind this: it's the return-to-risk ratio scaled by risk again, which is why the Kelly fraction tracks Sharpe ratio thinking rather than raw expected return alone. A high-Sharpe strategy earns a bigger Kelly allocation; a jumpy, low-Sharpe one gets sized down hard, even if its expected return looks attractive on paper.
Both versions rest on assumptions that rarely survive contact with real markets:
- Win probability or expected return is known with precision, not estimated from a small sample.
- You can reinvest and compound over a long, ideally infinite, sequence of bets.
- There's no friction: no taxes, no spreads, no slippage, no forced liquidation.
- Each bet or period is independent enough that past outcomes don't distort future odds.
None of those hold exactly in equity markets. That's not a reason to throw the formula out. It's the reason nobody serious runs full Kelly.
The deeper mechanic worth understanding: Kelly doesn't maximize expected wealth. It maximizes expected log wealth, which is a different target entirely. Maximizing plain expected value pushes you toward bet sizes that occasionally deliver enormous outcomes and, over enough repetitions, ruin. Maximizing expected log-wealth optimizes the growth rate of your compounding capital, which is what actually determines where you end up after 100 trades or 30 years.
The Kelly criterion maximizes long-run expected logarithmic growth, not short-term expected value, and it says nothing about limiting drawdowns along the way. That gap between "optimal growth" and "tolerable ride" is where almost every practical Kelly decision is made.
How to Compute Kelly Position Sizing Step by Step
Computing Kelly position sizing is a five-minute exercise once you have real inputs. Here's the sequence for both the binary case and the continuous stock case.
For a binary-style edge (options trades, event bets, discrete setups):
- Estimate your win probability p from a real track record, not a hunch. Twenty trades is not a sample; aim for triple digits where possible.
- Estimate b, your payout ratio, from actual average win size versus average loss size.
- Plug into f* = (bp − q) / b.
- Example: p = 0.55, b = 1.5 (win $1.50 for every $1 risked). f* = (1.5 × 0.55 − 0.45) / 1.5 = (0.825 − 0.45) / 1.5 = 0.25, or 25% of capital per this specific edge.
For a continuous stock position:
- Estimate μ, the expected excess annual return, from historical data, a valuation model, or a blended forecast.
- Estimate σ², the variance of that return stream, typically from trailing volatility.
- Divide: a stock with 8% expected excess return and 20% annualized volatility gives f* = 0.08 / 0.20² = 0.08 / 0.04 = 2.0, meaning 200% of capital, or 2x leverage.
That second example is the one that stops people cold. A realistic equity risk premium and typical volatility routinely push full Kelly above 100% allocation — the formula is telling you to use leverage. This is exactly why the continuous Kelly form implies leverage for ordinary stock-market inputs, and why almost nobody trades unscaled Kelly on equities.
Two practical warnings apply to both cases. First, Kelly is brutally sensitive to input error. Nudge p or μ up by a small margin and f* moves by a much larger one, because the formula amplifies your confidence, not just your edge. Second, calculator tools asking for "win rate," "average win/loss," and a "lookback window" are really asking you to commit to a sample size and a time horizon. Change the lookback from one year to five and your Kelly output can shift dramatically. A position-size calculator is useful for the arithmetic, but the arithmetic is only as good as the window you feed it.
Full Kelly vs. Fractional Kelly: What the Simulations Show
Run the same edge through full Kelly, half Kelly, and quarter Kelly across thousands of simulated paths, and a consistent pattern shows up: full Kelly wins on average terminal wealth but loses badly on the ride there.
A representative pattern from Kelly-style simulation work looks roughly like this:
- Full Kelly: Highest expected compound growth rate, but large drawdowns are common along the way, and terminal outcomes vary enormously between paths.
- Half Kelly: Captures the large majority of full Kelly's long-run growth rate while cutting peak-to-trough drawdowns by roughly half.
- Quarter Kelly: Noticeably lower growth than half Kelly, but with drawdowns mild enough that most investors could actually sit through them without panic-selling.
The mechanism behind that asymmetry matters more than the numbers themselves. Overbetting past the Kelly-optimal fraction doesn't just add volatility symmetrically. Bet at 2x your true Kelly fraction and the expected growth rate itself turns negative, even though every individual bet still has a positive edge. That's the trap: a real edge, sized wrong, becomes a losing strategy mathematically, not just emotionally.
Half-Kelly sizing is the most repeated heuristic in the practitioner literature for a reason: it tends to give up a small amount of theoretical growth in exchange for a large cut in variance. Ed Thorp's own writing on Kelly in finance reflects this exact tradeoff, favoring fractional application over the textbook-optimal number.
Full Kelly is defensible in narrow situations: a genuinely high-confidence, well-tested edge with a long personal or backtested track record, where the investor has both the capital base and the psychological runway to sit through a 60% drawdown without deviating from the plan. For nearly everyone else, that's a bad trade of theoretical growth for real-world risk of ruin.
The Estimation Error Problem and How to Guard Against It
Kelly's biggest practical risk isn't the formula. It's what you feed it. Overestimate your edge by even a modest margin and the output allocation can balloon, because f* scales directly with your inputs and doesn't know the difference between a real edge and a lucky sample.
Run the sensitivity yourself: if your true expected excess return is 6% but you estimate 9% from a short, favorable backtest window, your continuous-Kelly output inflates by 50% relative to the honest number. Estimation error is the single most cited practical limitation of Kelly sizing across trading and investing literature, and it's the reason full Kelly is treated as a theoretical ceiling rather than an execution instruction.
Several concrete mitigations show up repeatedly in how disciplined investors actually apply this:
- Use fractional Kelly as the default, not the exception. A 25 to 50% scaling factor absorbs a meaningful chunk of estimation error automatically, since you're deliberately under-betting relative to your point estimate.
- Apply Bayesian shrinkage to your inputs. Pull your μ and win-rate estimates toward a conservative prior (market average, sector average, or zero-edge) rather than trusting the raw sample number outright.
- Set a hard operational cap. Regardless of what the formula says, cap any single position at a fixed ceiling of total portfolio value, and separately enforce a fixed-percent floor per trade so a single bad estimate can't dominate the book.
- Stress-test the input, not just the output. Ask what f* becomes if your win rate is 5 points lower or your volatility estimate is 30% higher, and size to the more conservative of the two answers.
- Re-estimate on a fixed cadence, not whenever the current number looks favorable. Monthly or quarterly review keeps you from cherry-picking a window that flatters your edge.
Pro Tip: Treat your Kelly output as the ceiling of a range, not a target. If full Kelly says 40%, decide your policy is half-Kelly (20%) before you ever see that specific number, so the math can't talk you into oversizing on a good day.
Combining a fixed-percent risk rule with a Kelly-derived ceiling is exactly the layered approach described in position-sizing frameworks that blend risk-based and Kelly methods, and it's a more durable policy than trusting either method alone.
Extending Kelly to a Full Portfolio
Single-position Kelly gets complicated fast once you hold more than one asset, because the formula that ignores correlation will systematically over-allocate. Two positions that both look attractive individually but move together in a downturn aren't giving you two independent edges; they're giving you one edge, doubled in size and disguised as diversification.
The multivariate extension of Kelly replaces the single σ² with a full covariance matrix across your holdings, and the optimal fraction for each position now depends on how it moves relative to everything else you hold. Ignore that interaction and you'll size two correlated positions as if they were uncorrelated, which is the fastest way to end up more concentrated than you intended. Academic treatments of multivariate Kelly flag covariance estimation as the central practical obstacle, not the optimization math itself.
A few adjustments make the covariance problem manageable rather than paralyzing:
- Regularize the covariance matrix by shrinking estimates toward a simpler structure (like a diagonal matrix), which reduces the noise that comes from estimating hundreds of pairwise correlations off limited data.
- Use rolling estimation windows, commonly around two years, rather than a single static lookback, so the covariance structure can adapt without whipsawing on every recent data point.
- Cap effective leverage explicitly. Multivariate Kelly solutions frequently recommend gross exposure above 100% once correlations are netted out, and practitioners near-universally impose a hard leverage ceiling regardless of what the math prefers.
- Weigh rebalancing frequency against transaction costs. Frontiers research on practical Kelly implementation for equity portfolios found that outcomes are materially sensitive to how often you rebalance and how wide your covariance window runs; more frequent rebalancing captures the theoretical optimum more closely but eats into returns through costs.
Kelly portfolios built this way tend to land on the efficient frontier, but they sit less diversified than a standard Markowitz tangent portfolio built for the same expected return, which is a tradeoff worth naming explicitly before you adopt one.
A Step-by-Step Workflow for Conservative Kelly Sizing
Here's a workflow you can put into practice this week rather than a set of principles to admire from a distance.
- Gather inputs with a real sample. Pull at least one to two years of return data, or 30-plus discrete trade outcomes, before trusting any p or μ estimate. Smaller samples produce Kelly numbers that look precise and are actually noise.
- Compute full Kelly using the binary or continuous formula that fits your instrument.
- Apply a fractional scaling factor. Multiply by 0.25 to 0.5 depending on your confidence in the input quality and your personal tolerance for drawdown.
- Layer in a fixed-percent floor and a hard cap. A common policy pairs a 0.5 to 1% fixed-percent baseline risk per trade with an absolute ceiling (say, no single position above 15 to 20% of the portfolio), regardless of what scaled Kelly suggests.
- Document your assumptions in writing before you execute: what p or μ you used, what window it came from, and what the scaled f* was. This turns an emotional decision into an auditable one.
- Run a simple Monte Carlo check on the policy before committing real capital, simulating a range of outcomes around your estimated edge rather than just the point estimate.
- Monitor on a fixed schedule. Re-estimate inputs monthly or quarterly, not reactively, and recalculate your scaled Kelly figure each time.
- Pause the strategy if the edge decays. If realized win rate or return drifts meaningfully below your estimate for two consecutive review periods, cut sizing back toward the fixed-percent floor until the edge either recovers or the strategy gets dropped.
Pro Tip: Write your fractional-Kelly policy down before you ever calculate a live number. Deciding "I use half-Kelly, period" in advance removes the temptation to round up on a day when the formula happens to hand you a flattering figure.
Does Kelly Sizing Actually Work Historically?
The honest answer is nuanced: Kelly-style sizing shows real long-run growth advantages in backtests and simulations, but "works" depends heavily on which version you mean.
Full, unscaled Kelly applied mechanically to historical equity data tends to produce excellent compound growth on paper alongside drawdowns few real investors would tolerate in practice, which is precisely the finding that shows up across simulation and backtest research on equity Kelly portfolios. The growth numbers look great until you look at the path that produced them.
Fractional versions have a longer, quieter track record. Ed Thorp is the most-cited real-world proof point: he applied Kelly-derived sizing to both blackjack and hedge fund management for decades, and his own writing on the subject leans toward fractional application specifically because full Kelly's variance is harder to live with than its extra growth is worth. That's not an endorsement of a specific fund's returns; it's evidence that a serious, quantitatively sophisticated practitioner chose to scale down rather than run the textbook number.
The pattern that holds up across most empirical work: Kelly-informed strategies tend to outperform naive fixed-allocation approaches over long horizons when the underlying edge is real, but the outperformance shrinks and the risk of catastrophic miscalibration grows the closer you get to full Kelly. History rewards the discipline of the fraction, not the purity of the formula.
Kelly vs. Utility Optimization and Other Sizing Frameworks
Kelly is one member of a broader family of sizing frameworks, and it's worth knowing where it sits relative to the others rather than treating it as the only rigorous option.
Utility optimization is the more general approach: instead of maximizing log-wealth specifically, you choose a utility function that reflects your actual risk aversion, and Kelly turns out to be the special case where that utility function is logarithmic. An investor with a different risk tolerance profile might rationally choose a different utility function and land on a smaller (or occasionally larger) allocation than Kelly recommends, even holding the same beliefs about expected returns. Kelly isn't wrong in that framing; it's just one specific risk preference dressed up as a universal law.
They ignore how strong an edge is, but they also can't be talked into an oversized bet by a flattering input.
Volatility targeting sizes positions to hit a constant portfolio-level risk budget, which smooths returns across changing market regimes better than Kelly does on its own, since Kelly's output moves with your return estimate, not just your risk estimate.
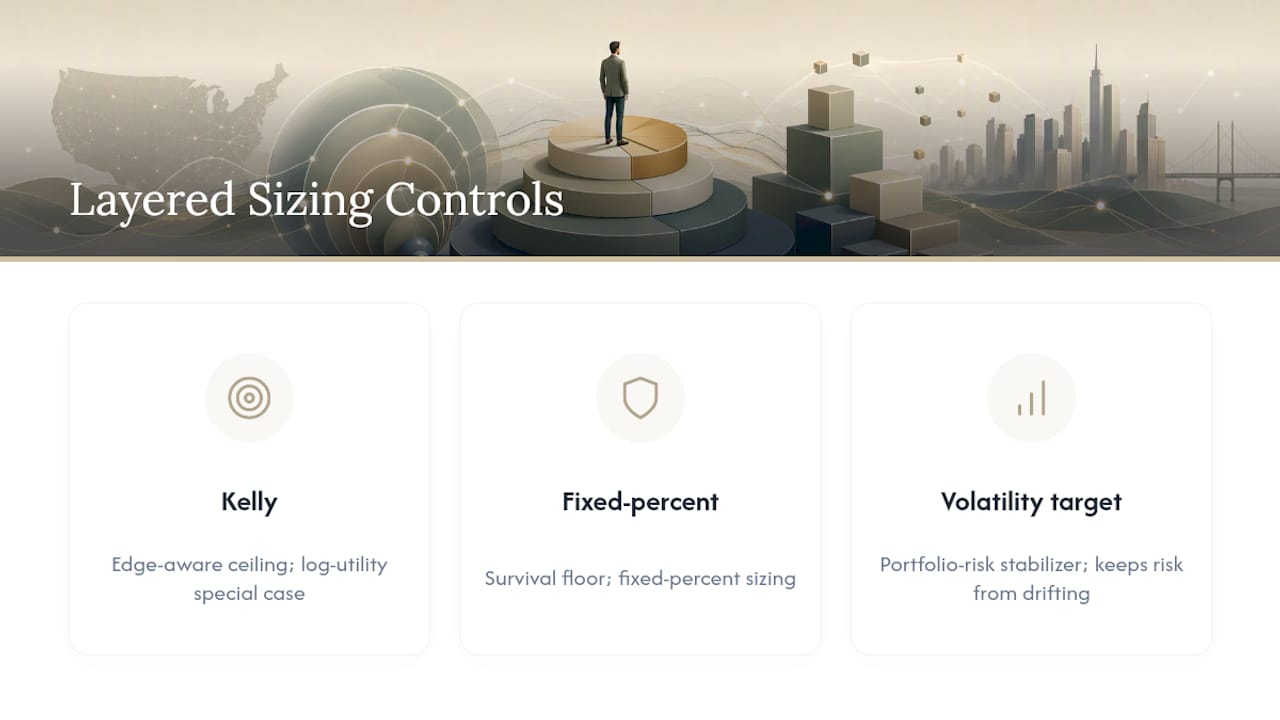
The practitioner consensus, reflected in how risk-based, Kelly, and volatility-targeted sizing get compared in real trading operations, isn't to pick one framework and discard the others. It's to layer them: Kelly sets the edge-aware ceiling, fixed-percent sets the survival floor, and volatility targeting keeps portfolio-level risk from drifting as market conditions shift underneath you.
Why Fractional Kelly Beats the Textbook Version in Practice
Most retail explanations of Kelly stop at the formula, hand you a number, and let you assume bigger is better because bigger is "optimal." That's the part of the conventional wisdom I'd push back on hardest: optimal for what, exactly? Full Kelly optimizes a growth rate calculated across an infinite series of bets with perfectly known probabilities. Nobody investing real money has an infinite horizon or perfectly known probabilities, so the "optimal" answer is optimal for a scenario that doesn't exist.
What actually matters is closer to a psychological constraint dressed up as a math problem. Half-Kelly or quarter-Kelly isn't a compromise for people who don't understand the math. It's the correct answer once you add the real constraint that Kelly's derivation leaves out: human behavior under stress.
The other underrated point is that estimation error, not market risk, is usually the thing that breaks a Kelly-sized position. You can be right about the direction of an edge and still get the sizing badly wrong because your sample was too short or too favorable. That's a data problem before it's a risk-management problem, and it's why sourcing better inputs, not tweaking the fraction, is often the highest-leverage fix available to you.
— Matt
How Oracle Investments Speeds Up Kelly-Style Position Sizing
Every step above depends on getting μ and volatility estimates right, and that's the slow part for most investors. Oracle Investments scores over 260 stocks on profitability, valuation, and financial health, which shortens the estimation work behind any fractional-Kelly policy considerably. Real-time portfolio tracking and instant side-by-side comparisons let you sanity-check an edge before you scale into it, rather than sizing off a single backtest window you're not sure you trust.
None of that replaces your own judgment about sample size, correlation, or how much drawdown you can actually tolerate. It just gets you to a defensible starting number faster, so more of your time goes to the scaling and monitoring decisions that matter most. If you're building out a conservative Kelly workflow, start by pulling up a few candidate positions on Oracle Investments and comparing their fundamentals side by side before you run a single sizing formula.
Sources
- Kelly criterion — Wikipedia
- Practical implementation of the Kelly criterion: Optimal growth rate, number of trades, and rebalancing frequency for equity portfolios — Frontiers (2020)
This article is general information, not a substitute for advice from a qualified financial advisor. Consult a qualified financial professional about your own circumstances before acting on anything here.